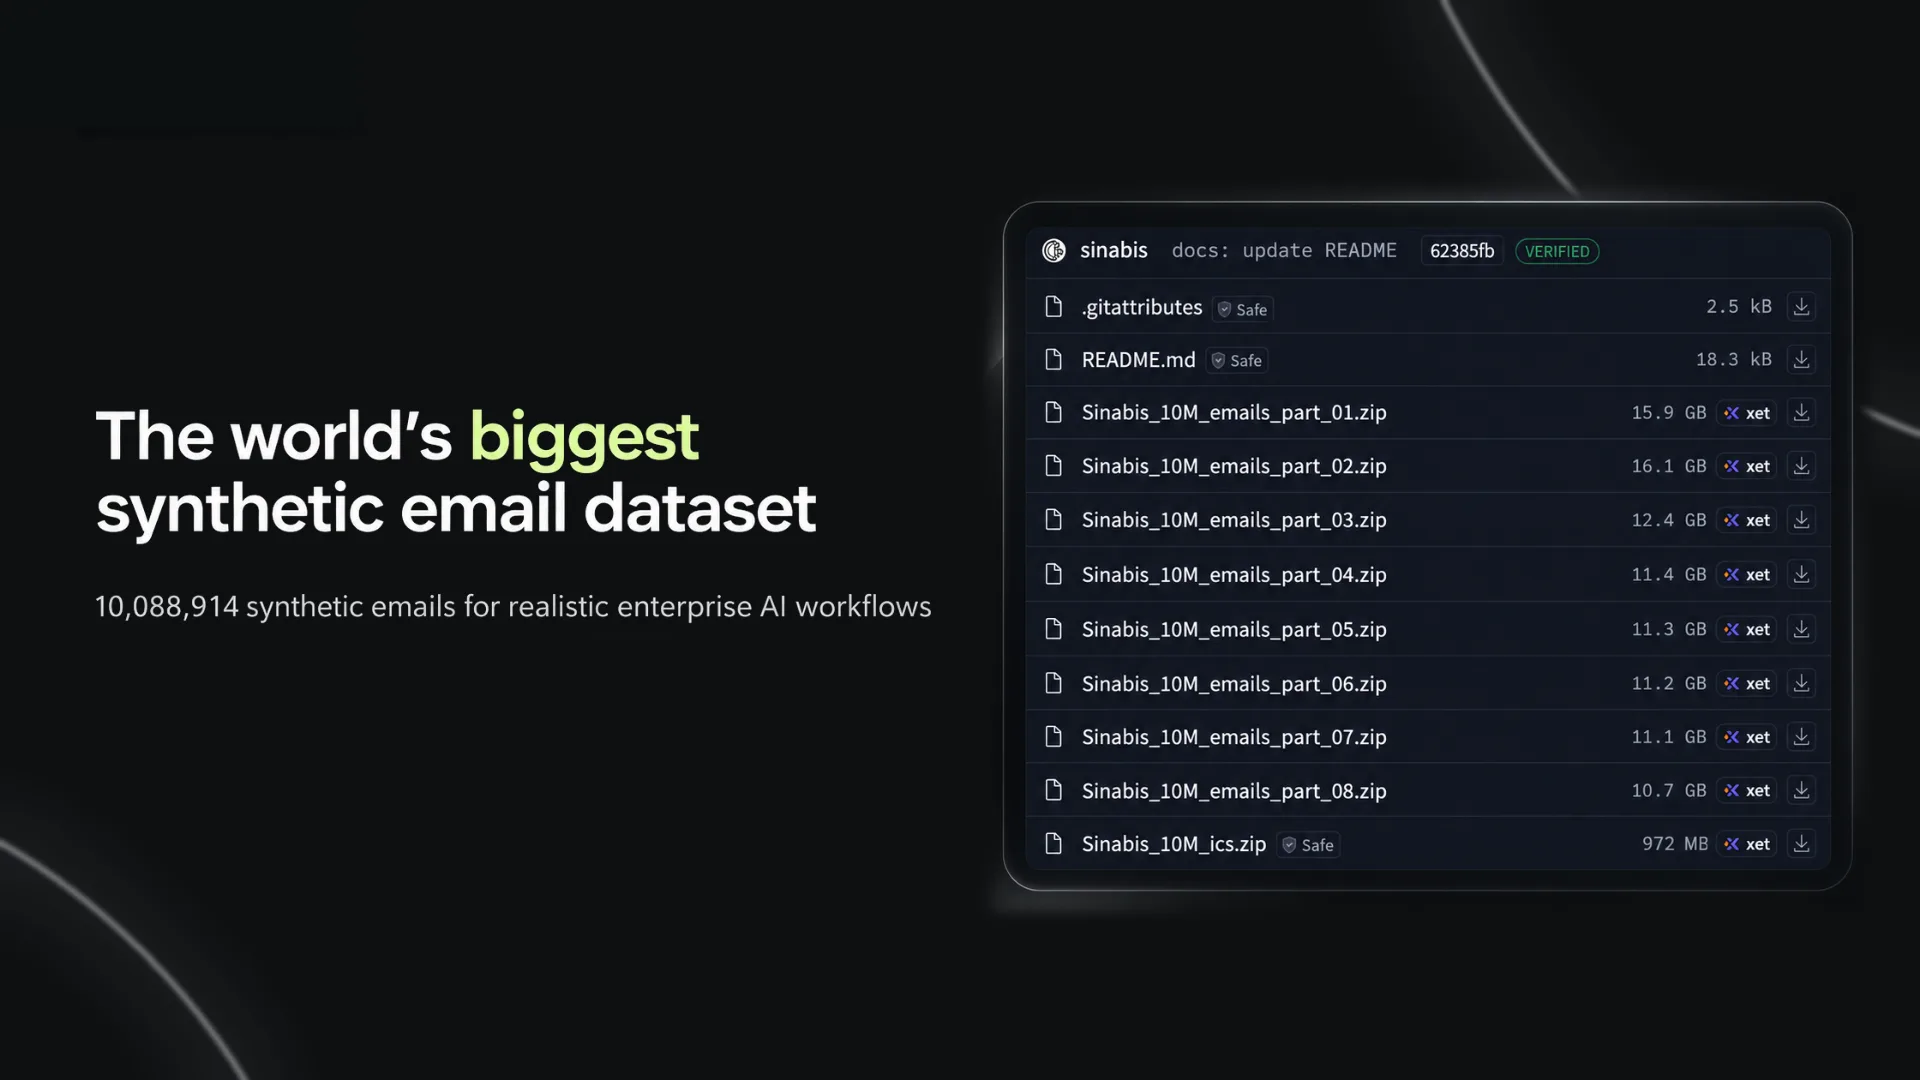
The World's Biggest Open Synthetic Email Dataset: 10 Million Emails, Free on Hugging Face
News & Industry · October 13, 2026
What Is a Synthetic Email Dataset?
A synthetic email dataset is a large set of emails that were generated instead of collected from real people. It looks and behaves like a real company mailbox, with threads, replies, attachments, and meeting invites, but it contains no real correspondence.
Why Use Synthetic Emails Instead of Real Ones?
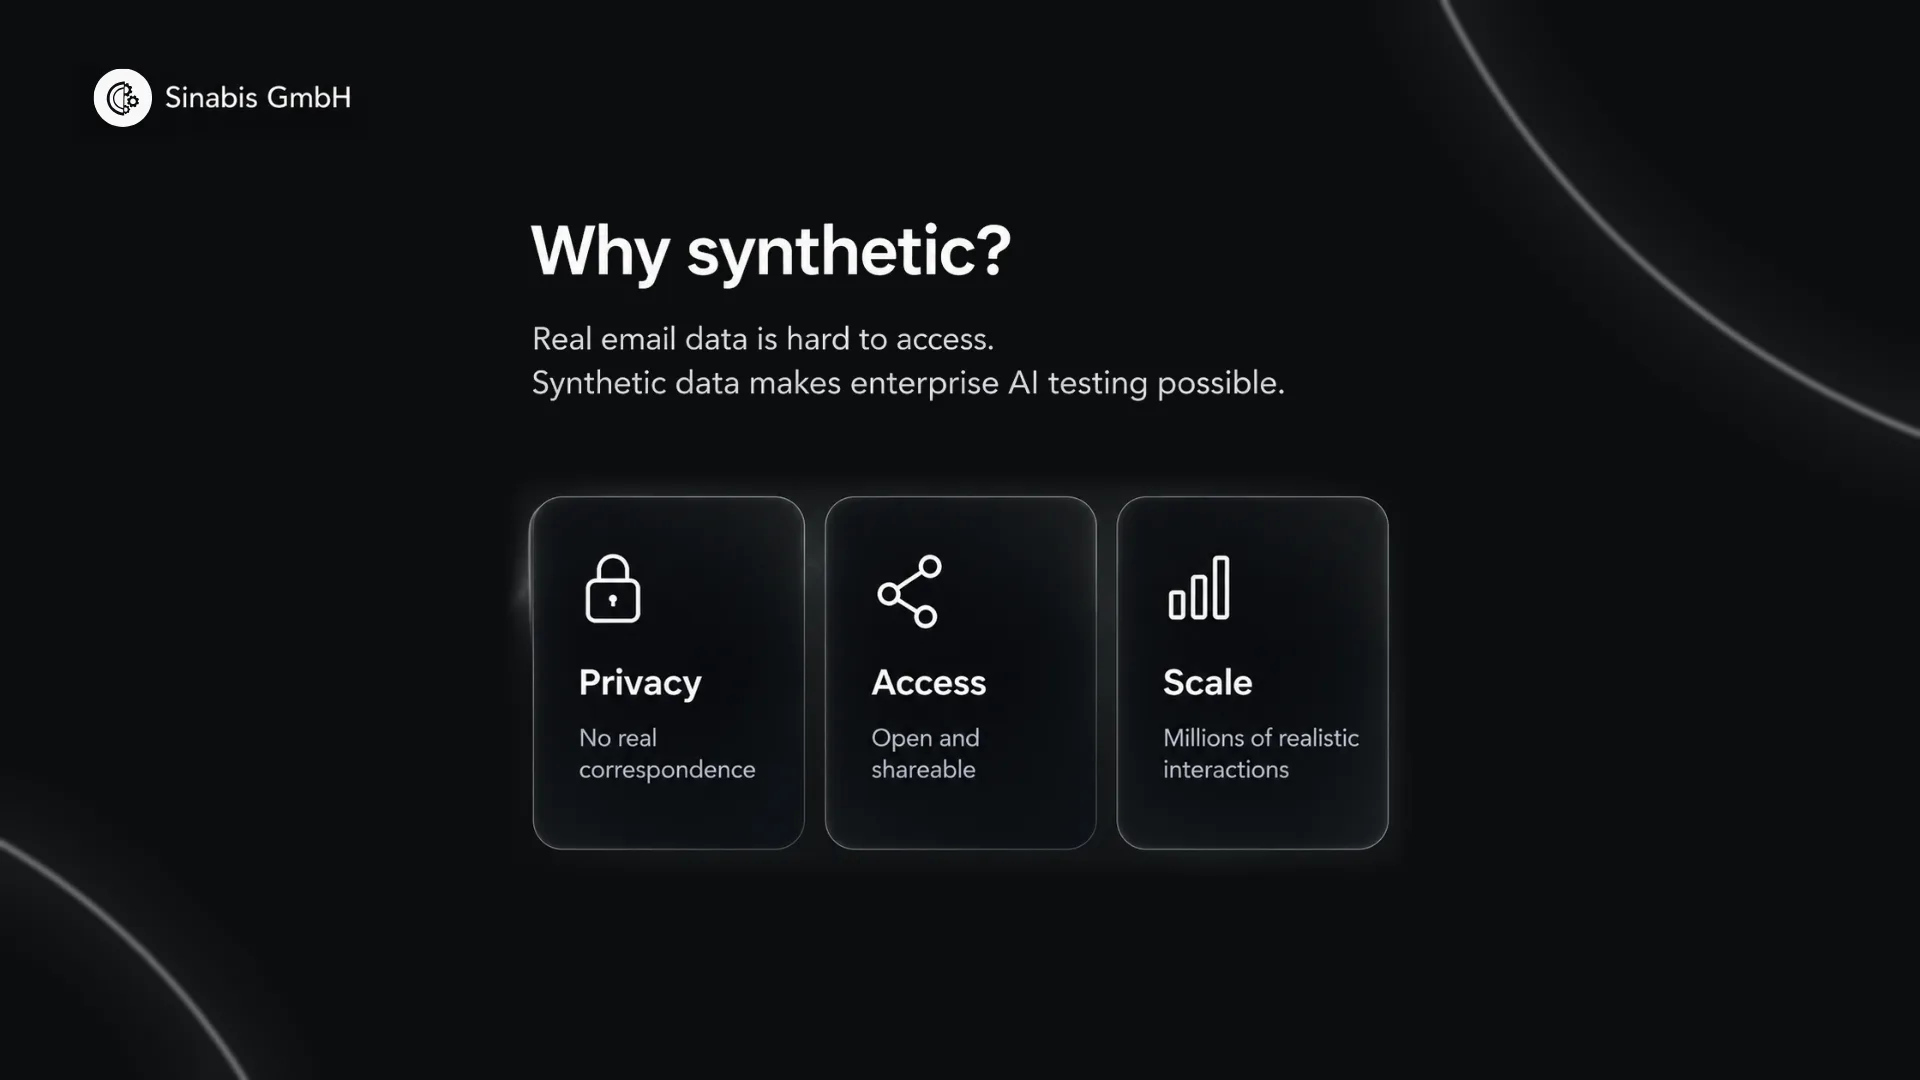
Real company email is valuable test data, but it holds personal details and confidential business information. Rules like GDPR limit how it can be used, so most teams never get to share it. Synthetic data helps in three ways.
- Privacy: there is no real correspondence, so nobody's data is exposed.
- Access: the dataset is open and easy to share.
- Scale: millions of realistic interactions let you test tools at real enterprise size.
What Is Inside the Sinabis Dataset?
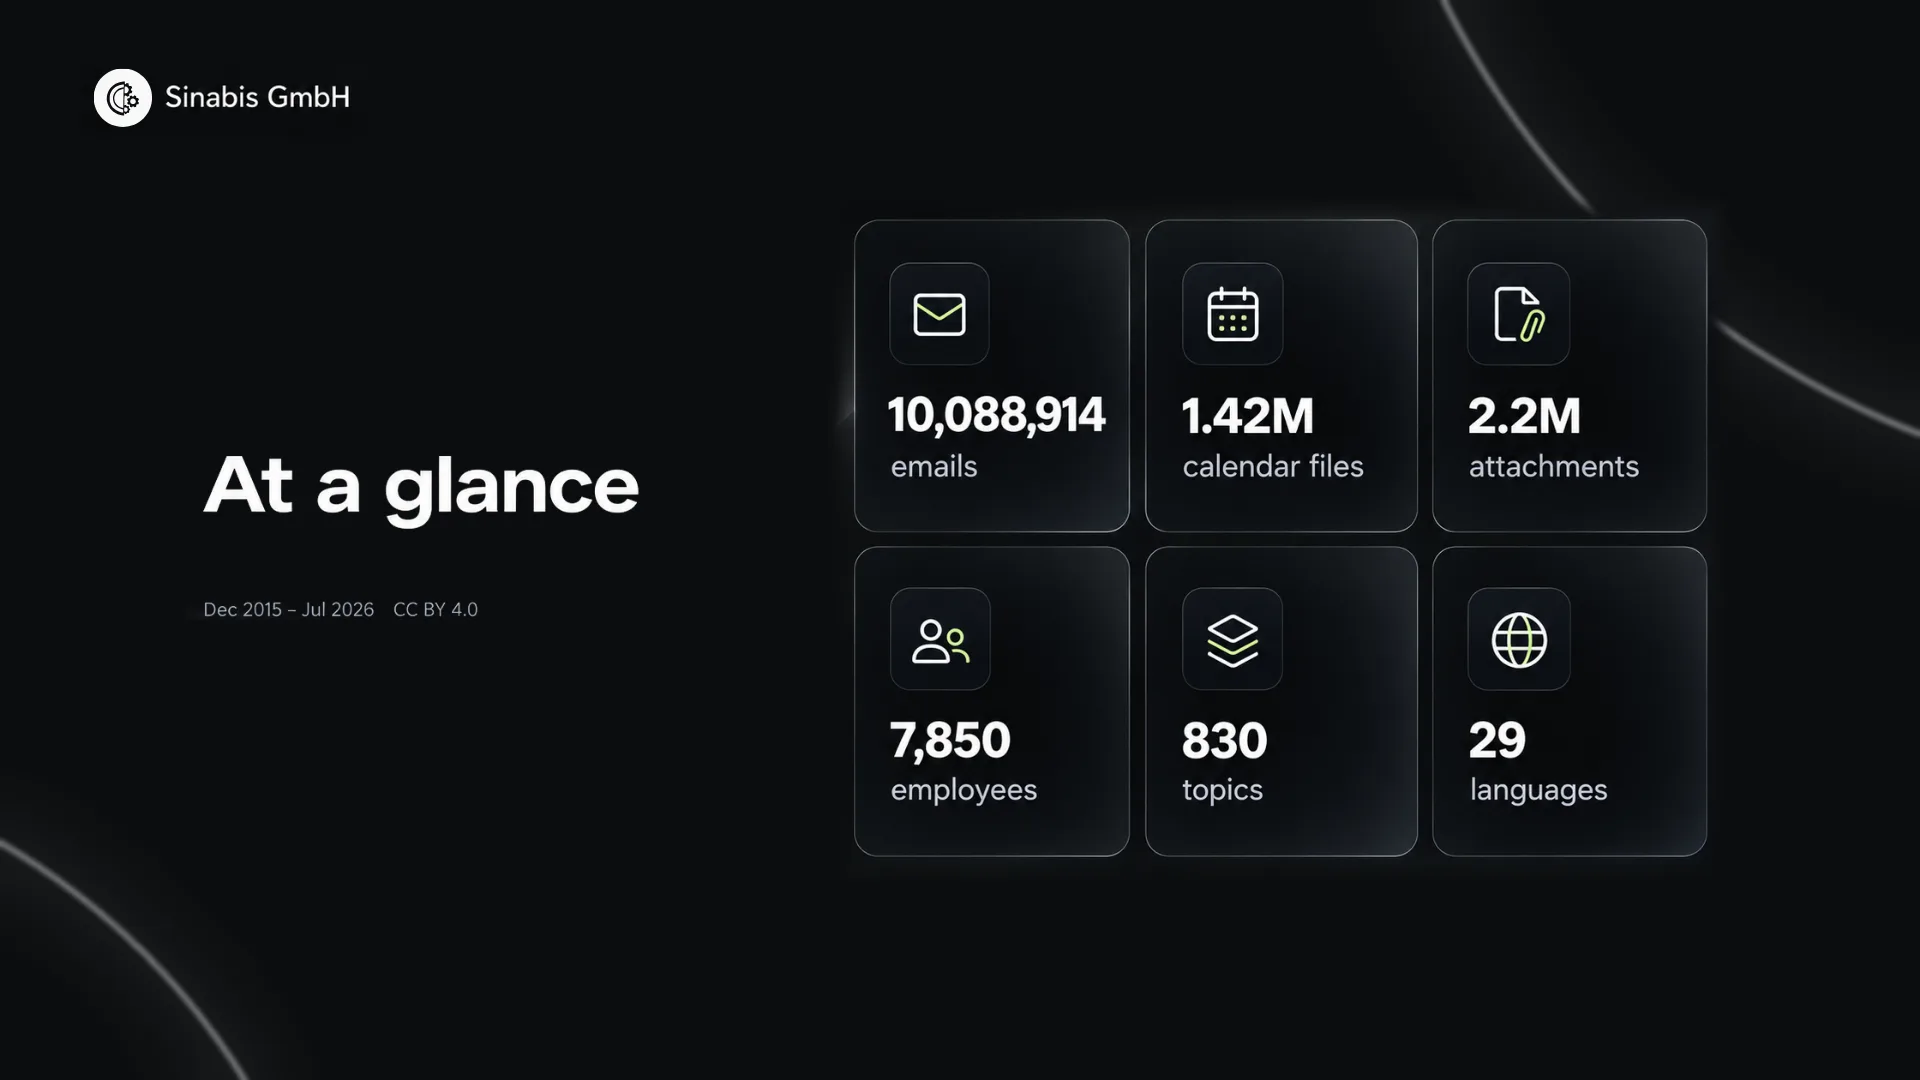
We built an entire fictional company with 7,850 employees and 830 topics. The emails run from December 2015 to July 2026.
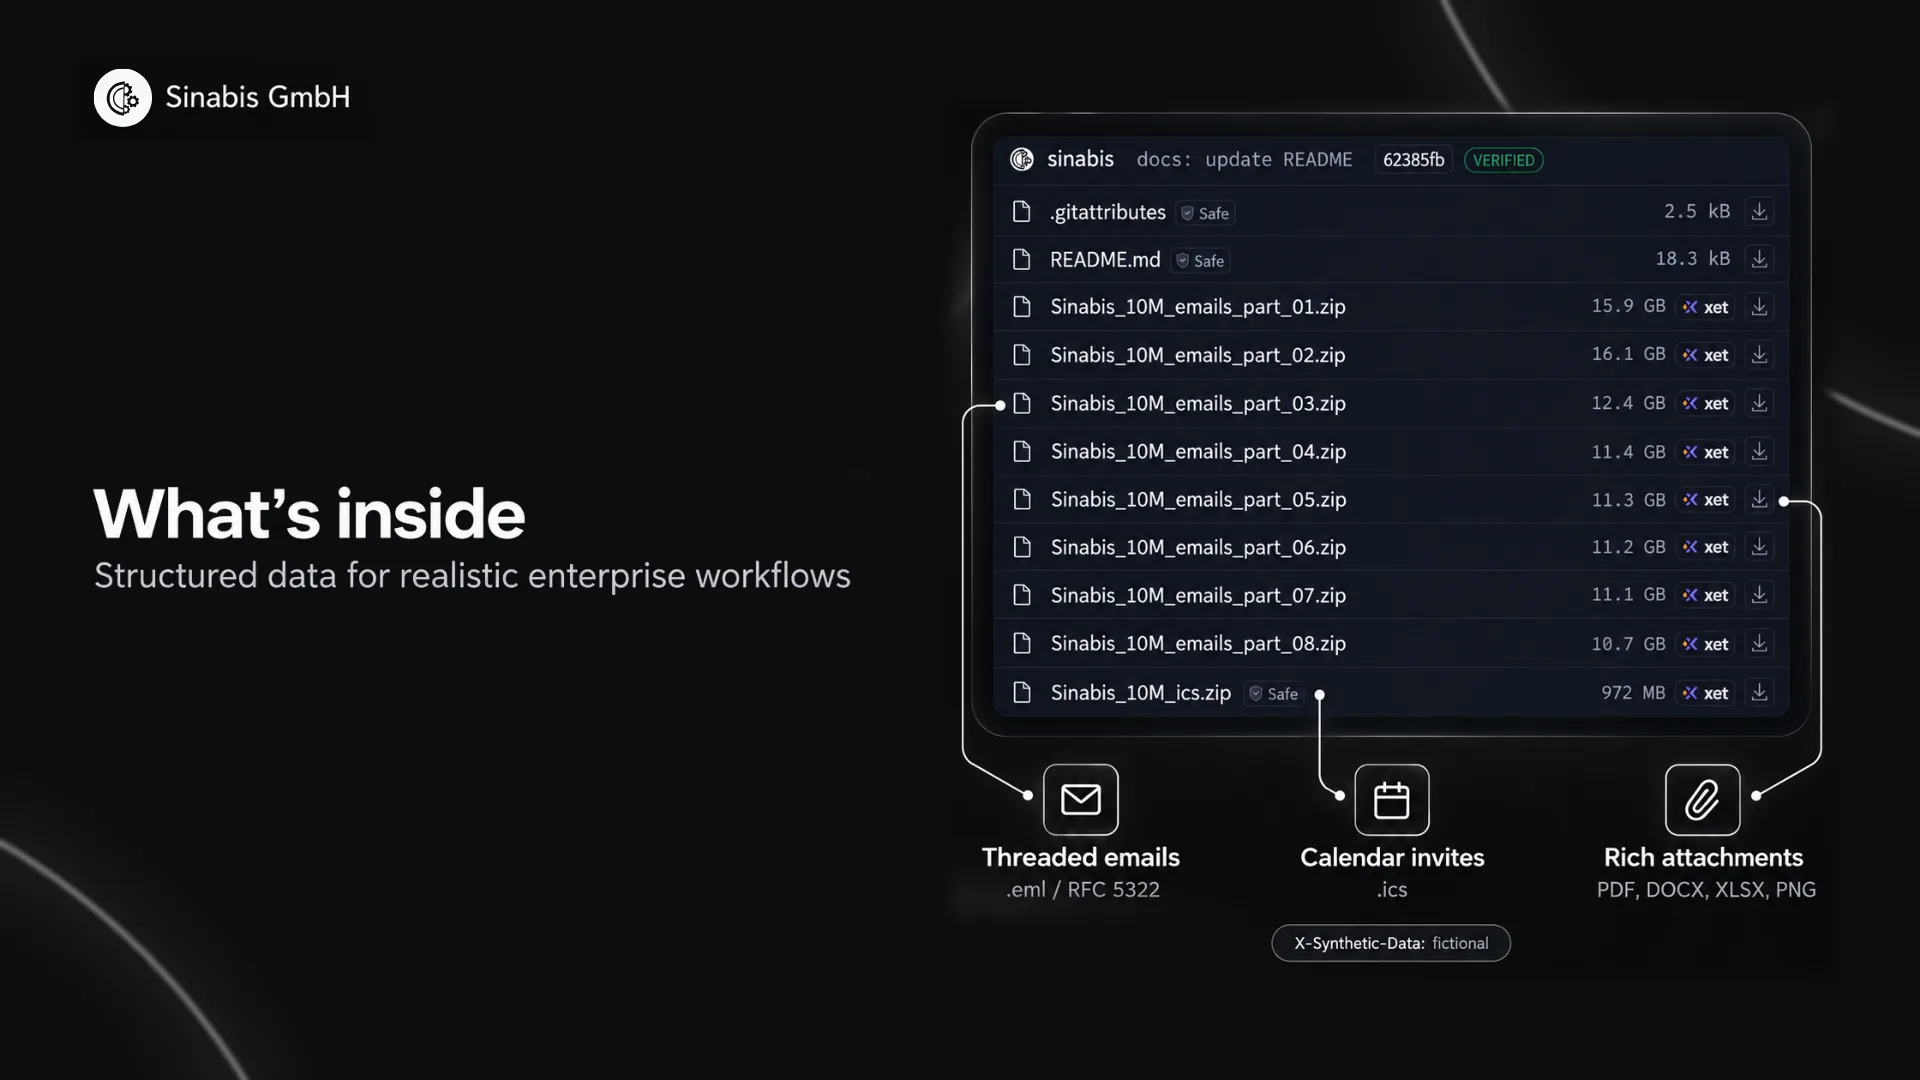
- Emails are .eml files that follow RFC 5322, with realistic threading.
- Calendar invites are .ics files that follow the iCalendar standard.
- Attachments come as PDF, DOCX, XLSX, and PNG files.
Every email carries the label X-Synthetic-Data: fictional. The eight email archives are about 11 to 16 GB each, roughly 100 GB in total, and the calendar archive is under 1 GB.
What Can You Use It For?
The dataset is made for realistic enterprise workflows.
- Testing AI agents that read, sort, and answer email.
- Training and testing email classification.
- Building and testing RAG systems over a large mailbox.
- Testing enterprise search across emails, attachments, and calendar files.
Can You Use It Commercially?
Yes. The dataset is released under the CC BY 4.0 license. You can use it for research, products, and commercial work. The only condition is attribution. Please read the license for the exact terms.
How Do You Get Started?
Open the Sinabis synthetic email dataset on Hugging Face: https://huggingface.co/datasets/sinabis-group/sinabis-10m-synthetic-emails and read the README.- Download one email archive first and look at the files.
- Run your tool against it, then add more archives.
We built this dataset because our customers face the same problem: they cannot share real email to test AI tools. If you want to see how Sinabis works with large email archives, read about our data processing or get in touch.
Frequently Asked Questions
What is the Sinabis synthetic email dataset?
It is an open collection of 10,088,914 fictional emails, with 1.42 million calendar files and 2.2 million attachments, in 29 languages.
Is it free for commercial use?
Yes. It uses CC BY 4.0, which allows commercial use with attribution.
Is any of the data real?
No. Every message belongs to a fictional company and is marked X-Synthetic-Data: fictional.
Which file formats are included?
Emails are .eml files, calendar invites are .ics files, and attachments are PDF, DOCX, XLSX, and PNG files.
How big is the download?
The email archives are roughly 100 GB in total, split into eight parts. The calendar archive is under 1 GB.
→ Learn more: www.sinabis.com
Sinabis Analytics GmbH · X64 Forensic GmbH · X64 Systems GmbH
Fatima Naz